Audio Generation
Summary: XBRUSH's audio generation provides four features: text-to-speech (TTS), AI music composition, sound effects, and lip-sync. You can generate various types of audio content using text or video as input.
What is Audio Generation?
Audio generation is XBRUSH's feature for creating voice, music, sound effects, and lip-sync audio using AI. It supports four sub-features: TTS for reading text aloud, music composition in your desired genre, automatic background sound generation for videos, and lip-sync that combines an image with audio.
Audio Generation Overview
- In the Workspace input box, switch to Direct mode and select the Audio tab.
- An image, video, or audio file may be required depending on the feature.
- Four sub-tabs are available: Voice / Music / SFX / Lip Sync.
- Voice reads text aloud.
- Music composes a piece of music based on a text description.
- SFX generates sound effects that match an uploaded video (or from a text description).
- Lip Sync combines an uploaded image with voice audio to create a video with synchronized lip movements.
- Each sub-tab is a compact strip inside the input box: the prompt line (where the sub-tab takes one), the option chips, and a bottom row with Chat | Direct, "Generating starts a new session", Run · New line, and the action button with its credit cost.
Voice (Text To Speech)
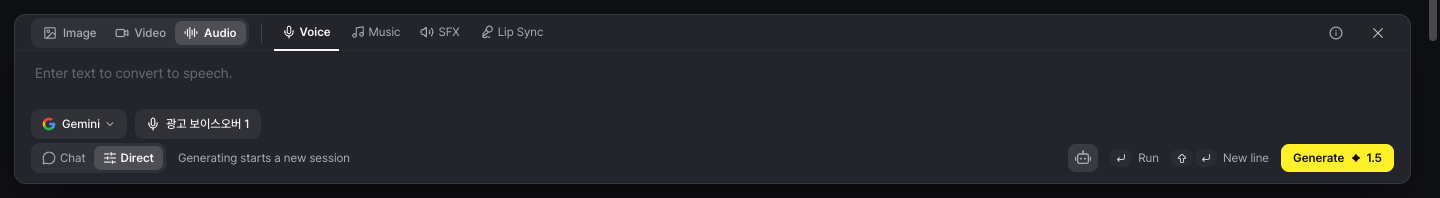
Audio › Voice: the prompt line ("Enter text to convert to speech."), the Gemini engine chip, the voice chip 광고 보이스오버 1, and the Generate button.
- Converts text to speech.
- The default AI engine is Gemini, and the default voice is 광고 보이스오버 1 (a Korean-named voice, "ad voiceover 1"; the name stays in Korean even in the English UI). Click the voice chip to pick a different voice if you like. The available voices and options (such as filters or sliders) depend on the engine you select.
- Enter the text you want read aloud and click Generate. The credit cost is shown on the Generate button.
Music
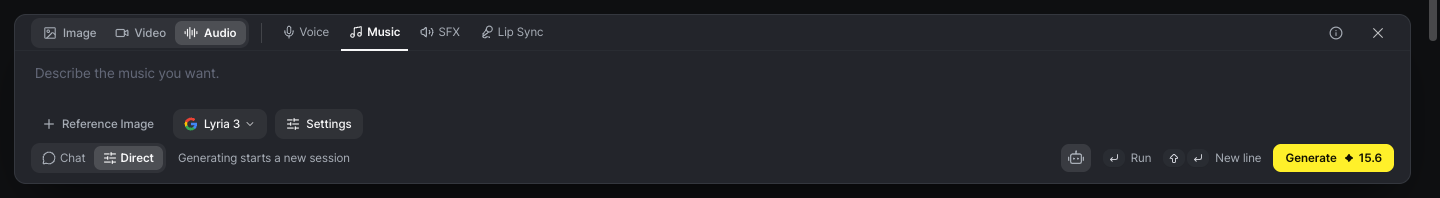
Audio › Music: the prompt line ("Describe the music you want."), + Reference Image, the Lyria 3 engine chip, Settings, and the Generate button.
- Generates music.
- The AI engine is Lyria 3. You can optionally upload a Reference Image to guide the music, and Settings holds additional music options.
- Enter your desired genre, instruments, and mood as text, then generate.
- For example, entering "Compose a fingerstyle piece for classical guitar with a melody" will produce a guitar instrumental.
Sound Effects
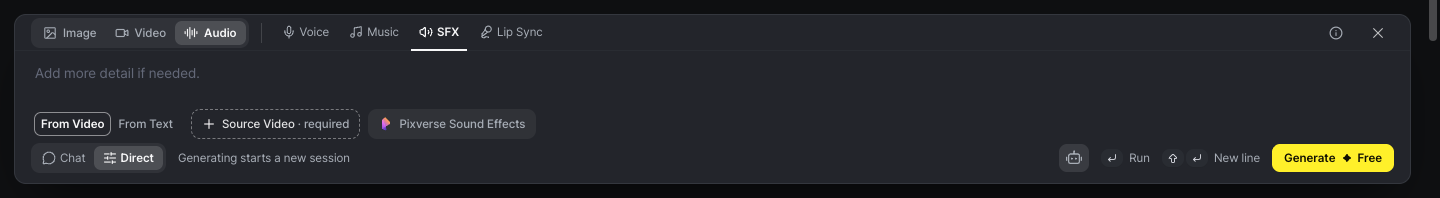
Audio › SFX: From Video | From Text, + Source Video · required, the Pixverse Sound Effects engine chip, and the Generate button. The prompt line reads "Add more detail if needed."
- Generates sound effects. Choose From Video or From Text.
- In From Video mode, upload the video with + Source Video · required, add more detail if needed, then click Generate. The engine is Pixverse Sound Effects.
- The system creates sound effects that fit the uploaded video.
Lip-sync
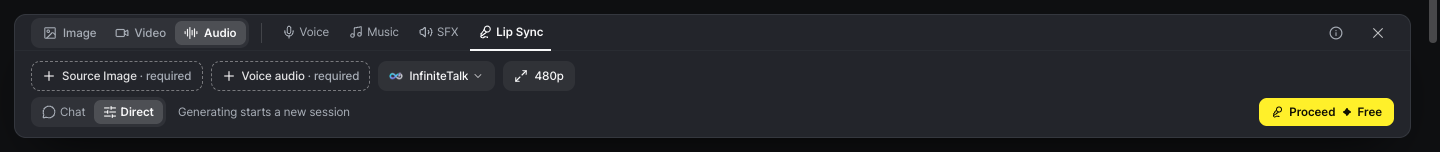
Audio › Lip Sync: + Source Image · required, + Voice audio · required, the InfiniteTalk engine chip, 480p, and the Proceed button. There is no prompt line.
- Combines audio with an image to create a synchronized video.
- Upload an image with + Source Image · required and the voice with + Voice audio · required, then click Proceed to generate a lip-synced video. The AI engine is InfiniteTalk, and the resolution chip defaults to 480p (click it to choose another).
- The final output matches the length of the input audio.
Next Steps
- Video Generation
- Editor — Create presentations using images and videos
- Social Media — Publish results to your social accounts